Morph: Flexible Acceleration for 3D CNN-Based Video Understanding
Scope
Video models add a temporal dimension to convolution, producing large and changing working sets. Morph adapts how each layer is mapped so the hardware can remain efficient across those shapes.
Abstract
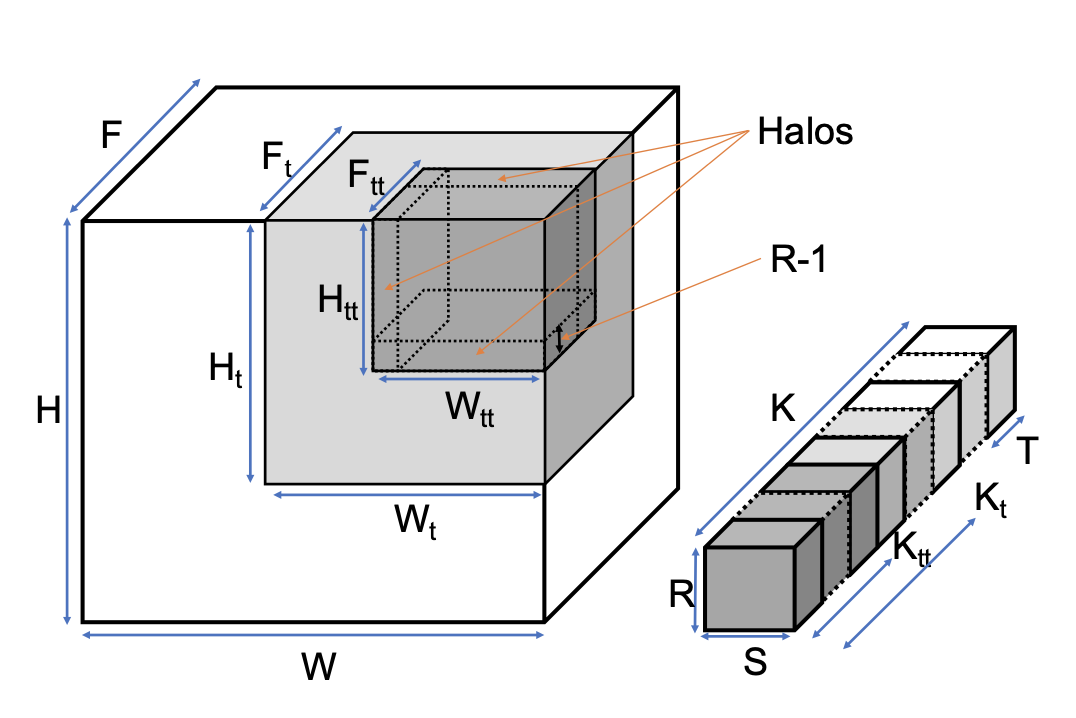
Accelerator research had focused mainly on 2D CNNs for images, while 3D CNNs used in video recognition received less attention. Their higher dimensionality and variable memory footprint make fixed mappings inefficient. Morph combines a design-space study with a flexible architecture for 3D convolution. It changes how compute and storage resources are used across layers to preserve utilization for diverse video networks.