UCNN: Exploiting Computational Reuse in Deep Neural Networks via Weight Repetition
Scope
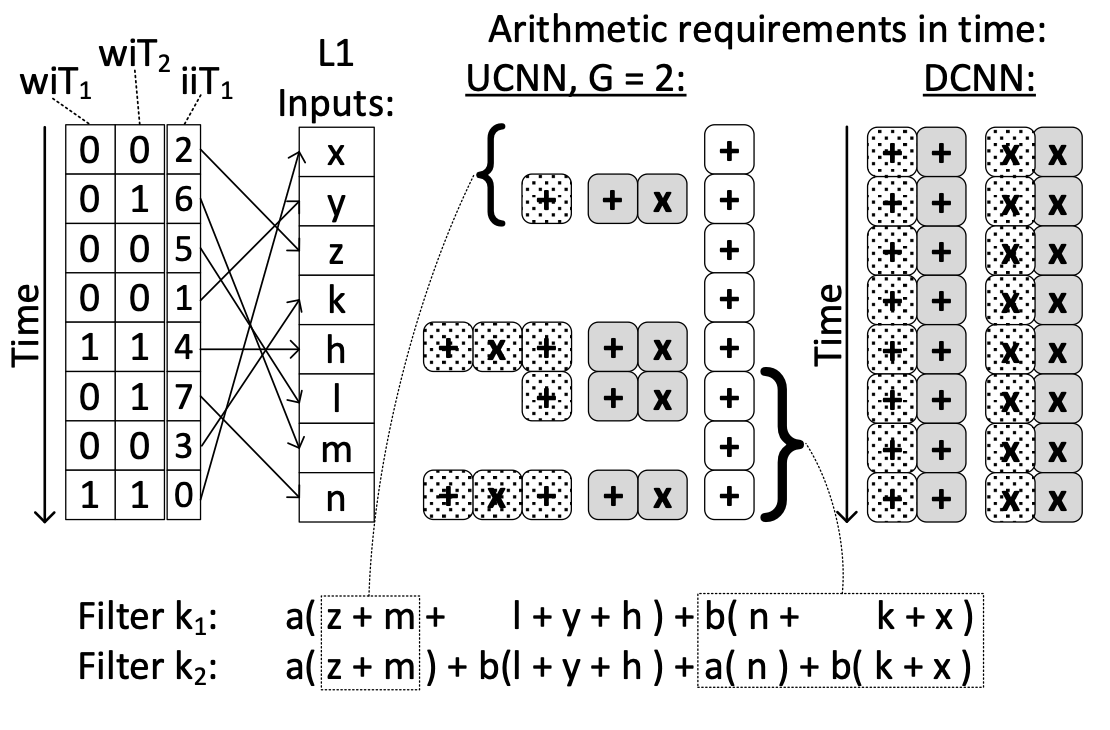
Quantized neural networks repeat many weight values, not only zero. UCNN reuses partial computations associated with those repeated weights.
Abstract
CNN inference consists largely of dot products between weights and activations. UCNN generalizes sparsity-based acceleration by treating every repeated weight as an opportunity for reuse. Algebraic reassociation reduces repeated computation and compresses model storage, while conventional sparsity optimizations remain available. Evaluation across three CNNs shows 1.2×–4× lower throughput-normalized energy with a 17–24% processing-element area overhead.